

- Structural: did the change touch traffic, and how badly? HIGH, MEDIUM or LOW IMPACT.
- Eval: was that traffic working? REGRESSION LIKELY, EXPECTED IMPACT or CLEAN.
See a sample report
You can see the report before you instrument anything. Seed a demo into your workspace. It needs no agent code or model key:[Demo] , and decimalai demo reset removes it.
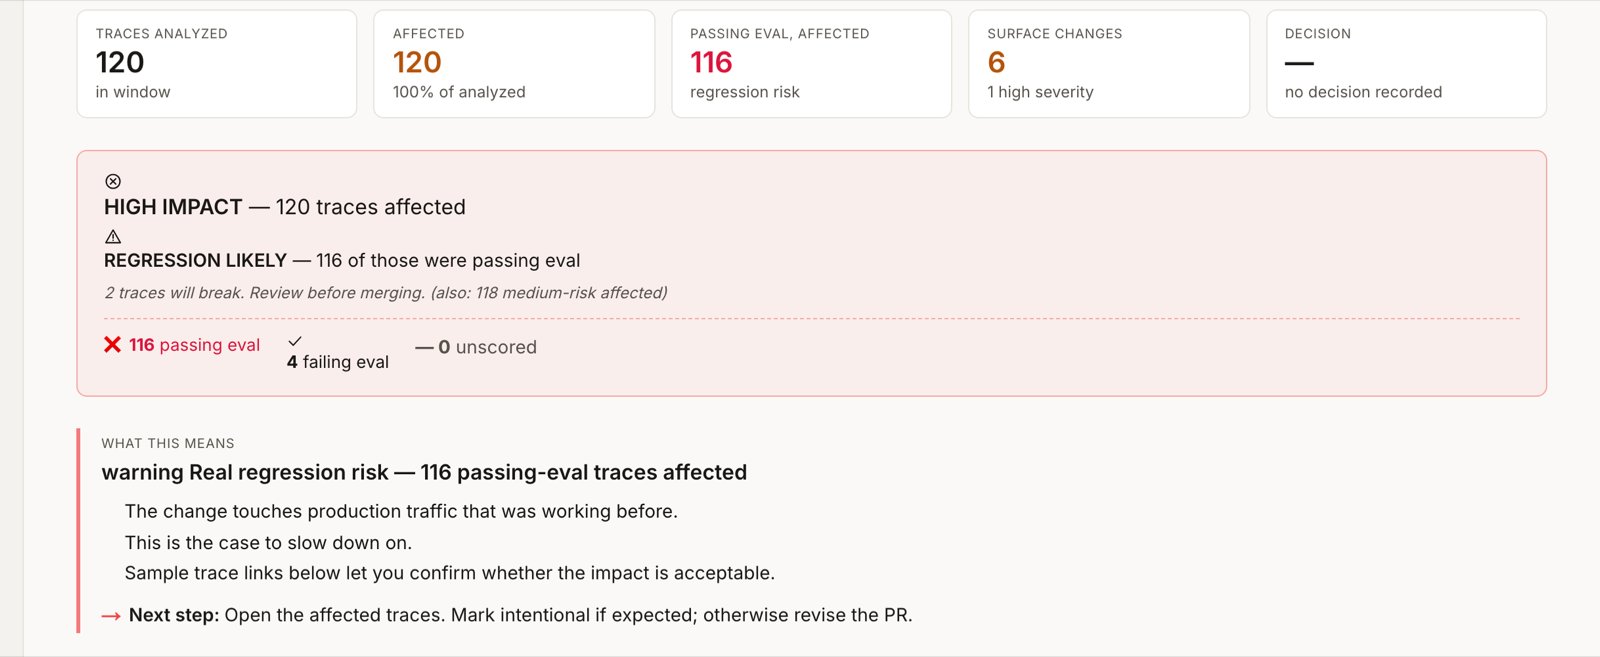
The seeded impact report
api-key and the Action runs in fixture mode: it posts the comment on your PR from a committed sample report, labelled as sample data, with no signup. The job never fails in this mode. A workflow with one step, uses: decimal-labs/regression-check@v1, and the pull-requests: write permission is enough.
Setup
Trace your agent in production first (Tracing). Until traces exist, the check has nothing to measure against.Step 1: Add a thin init entry point
The Action doesn’t build the manifest itself. A step before it runs your agent’s setup code and uploads the result, so the manifest comes from the same objects production uses. Createscripts/init_for_decimal.py:
chain= and pass tools, prompts, models and output_schema yourself, the same arguments register_manifest() takes. With LangGraph’s create_react_agent, chain= finds the tools but not the model or prompt, so pass prompts and models as well.
Step 2: Add the GitHub Action workflow
Create.github/workflows/decimal.yml:
$GITHUB_OUTPUT is per step, so the Action can’t see what an earlier step wrote unless you pass it through. A workflow without the id: and candidate-manifest-id: lines fails with the same “No candidate-manifest-id” error, whichever template it came from.
Step 3: Add the secret
In your GitHub repo, open Settings → Secrets and variables → Actions → New repository secret.- Name:
DECIMAL_API_KEY - Value: your API key from Settings → API keys
Read the report
If the agent has no earlier manifest, the first PR records its manifest as the baseline, posts FIRST RUN, and passes. Later PRs get a report like this one, shortened from the sample report that fixture mode uses:The structural verdict
The eval verdict
The eval verdict never changes the job result. Scores come from your evaluators, so with no scored traces it always reads CLEAN.
How severity is determined
Tool changes count the traces that called the tool, and skill changes count the traces that activated the skill. Prompt and model changes count every trace in the window: the check can say they may all change, but not whether answers get better or worse. For a model swap,
behavioral-check answers part of that.
Only these changes move the verdict. Changing a sub-agent or the output schema creates a new version, but the check doesn’t grade it.
What to do with the result
How the two verdicts combine
When the job fails
With the defaultfail-on: high, a HIGH IMPACT verdict fails the job. You can:
- Fix it. Restore the tool, parameter or skill and push.
- Ship it on purpose. Set
fail-on: nonein the PR’s workflow file for that run, say why in the PR, and put it back afterwards.
After merge
When your deployed agent registers the merged manifest and sends traces, that manifest becomes the baseline for later PRs.Find what broke
A change can pass the PR check and still hurt production, because a model swap or prompt rewrite changes behavior that a structural diff can’t predict. This view shows how each shipped version really performed, from traces you already recorded, and spends no tokens. The PR comment calls this post-deploy bisect. Open Agents → your agent → More → Regression checks. Live performance timeline is at the top, above the impact reports. It has one bar per manifest version, and you choose the metric and a window of 1, 7, 14 or 30 days:
Regression detected appears when the most recent version is more than 10% worse than the version before it, and both have at least 50 traces. With fewer, a note says there isn’t enough data and thin bars are hatched. Only the latest pair is tested, so if you shipped three versions today, compare the bars by eye. To see it populated, open
[Demo] support-agent after running the demo above.
1
See what changed
view what changed in the banner opens Code changes at the diff between those two versions.
2
Raise an alert
Mark as regression in the banner, or a click on any bar, creates an alert and fires your webhook if you’ve configured one. A background job also does this about once a day, for pass rate only, over the last 7 days.
3
Decide
- Revert. View revert checklist on the alert lists what to undo in your code and links the PR that introduced the version, when there is one. DecimalAI doesn’t deploy your code. For a prompt or skill it serves, see roll back.
- Fix forward. A new PR gets a check as usual, and its version gets its own bar once deployed.
- Accept. Resolve closes the alert. Acknowledge says someone is looking at it.
GET /api/v1/agents/{agent}/regression-timeline takes metric and window_days (up to 90). POST /api/v1/regression-alerts takes agent_name, manifest_id, and optionally metric and reason.
Configuration options
Inputs
Outputs
Blocking behavior
A failed job blocks the merge only if GitHub branch protection requires it. Each check counts against your plan’s monthly limit (Pricing).
Behavioral verification
behavioral-check tests whether a model swap really changes answers. It takes a small sample of the affected traces (at most 10), re-sends one recorded model call from each to the new model, and compares the answers. This is a single stateless model call, not your agent, so no tools run.
It runs only when the diff contains a model change, and it never fails the job. It works only when the old and new models share a provider, and that provider is OpenAI or Gemini. Otherwise the comment says so.
Running outside CI
You can run the same analysis from your laptop or another CI system. Outside GitHub Actions,flush_manifest_for_ci() writes the ID to ./decimal_manifest_id.txt, and the CLI reads it from there:
--dry-run computes the report without saving it or using quota. The CLI exits 0 below the fail-on level, 1 at or above it, and 2 on an error, and the CLI reference has every option. From a script, POST /api/v1/regression-check takes agent_name and candidate_manifest_id, with ?dry_run=true as a query parameter. Run new check on the Regression checks page does this from the dashboard.
What can go wrong
The manifest extraction step fails
Your init script raised an error, so the job fails at that step and the Action never runs. Usuallybuild_agent() needs something CI doesn’t have, such as a database or a key. Stub what it needs, and use placeholder values for required environment variables.
No comment on the PR
Check that the workflow grantspull-requests: write. A failed comment only logs a warning, so the job can be green with no comment. On PRs from forks, the default token can’t comment, so set github-token.
A report that doesn’t describe your PR
The check compares manifest versions. A PR that leaves the manifest as it is, including one that only edits prompt text, registers no new version (Manifests). The report then shows the current version against the one before it, not your PR, and it can fail the job on a change that has already shipped. A prompt edit is graded when it ships with a tool, model or skill change. To test a prompt edit alone, use Evaluations, then watch the timeline after you deploy.”First run” on more than one PR
The check stays on first run until the agent has a second manifest version.Empty or small impact reports
- Has this agent sent traces in the window? If not, the verdict is
unverified. Widentrace-window-daysif the traffic is older. - Does
agent-namematch bothflush_manifest_for_ci(agent_name=...)and the name your production agent uses? A mismatch finds no traces.
HIGH IMPACT on a change that should do nothing
A tool whose content changes with no parameter added or removed reads as HIGH. The manifest is probably capturing something that changes on its own, such as a value generated at runtime. See Manifests.Stale baseline
The baseline is the manifest yours was registered on top of, skipping PR builds that never served a trace. If reports look exaggerated, check that the deployed agent runs the SDK in its normal mode, notmanifest_only.
How this compares to eval-based regression checks
An eval-driven check re-runs your eval suite on the new version and compares pass rates. DecimalAI looks at what changed and which real traces it reaches.
The two approaches are complementary. Use both if you want behavioral verification on the eval surface, and use DecimalAI alone if you don’t have an eval suite yet.
What’s next
Manifests
What manifests capture and how versions work.
Evaluations
Test a change, including a prompt edit.
Troubleshooting
The Action isn’t commenting, or says “no manifest”?