

What a run shows about skills
A run’s Overview tab has a Recorded skills section with three rows: Offered, Delivered and Loaded. How skills reach the model defines them. On one run, read them like this:
Two more rows can appear. Routing decision is the id of the ranking this run used. Experiment says which group the run was in.
Under those rows, each recorded skill has its own line:
- Explicit load recorded means the skill is on the run’s Loaded list. Activation record means it was recorded another way, such as your code declaring it.
- Skill version v3 is the version this run received, which may not be today’s. Version not recorded means the run didn’t say.
- Details shows the recorded version ID and content hash, and Copy evidence copies them.
What the API returns, and how each step is detected
What the API returns, and how each step is detected
GET /api/v1/traces/{trace_id} returns the same three steps:active_skills holds the loaded skills with the version of each, plus any skill your code declared. null means the step wasn’t reported, and [] means it was reported and empty.Loaded comes only from a direct event: the model calls load_skill, a framework’s own skill loader hands it a skill, or your code declares it.Offered and Delivered come from DecimalAI’s own list when DecimalAI built the prompt. Otherwise, on the generic tracer, LangChain, OpenAI Agents and OpenTelemetry, the SDK matches system and developer messages against the skills it knows. A name alone, such as ## Skill: code-review, means Offered. At least 60% of the skill’s body lines means Delivered.Which prompt a run used
An agent built withagent_config() records, on each run, the prompt that run was given: its source ("decimalai", or a fallback value when no saved prompt was used), the saved version number, the template’s content hash, and the names of the variables it filled. Variable values are never recorded. When DecimalAI could not serve the agent’s skills, the reason is recorded too.
The API returns these as prompt on each trace, or null when the run recorded none. GET /api/v1/traces?prompt_version=3 lists the runs whose agent ran saved version 3; a handoff target’s prompt doesn’t count as the run’s own.
In the dashboard:
- A run’s page shows the version in its header, and a Prompt section with the source, hash and variable names, linked to Other traces on this version.
- The agent’s Traces tab has a Prompt column and a filter by prompt version. Its Version column is the agent’s code version, which a prompt edit doesn’t change.
- Prompt & skills links each saved version to Traces on this version.
The rest of a run
A run has this shape:- Traces are what the rest of DecimalAI works on: evaluators score them, compatibility gives them verdicts, and datasets are built from them. A trace belongs to one agent, and normally one manifest. Some compatibility screens and routes say episode, which means the same thing.
- Spans nest through
parent_span_id, and each has aspan_type:agent,llm,tool,retrieval,router,judge,handoff,guardrail,memory,planningorother. - LLM calls hold the messages sent, the output and the tokens. Training rows are made of them.
- Sessions group the runs of one conversation. Runs that share a
session_idbelong together.@decimalai.trace()takes it.
Find a run
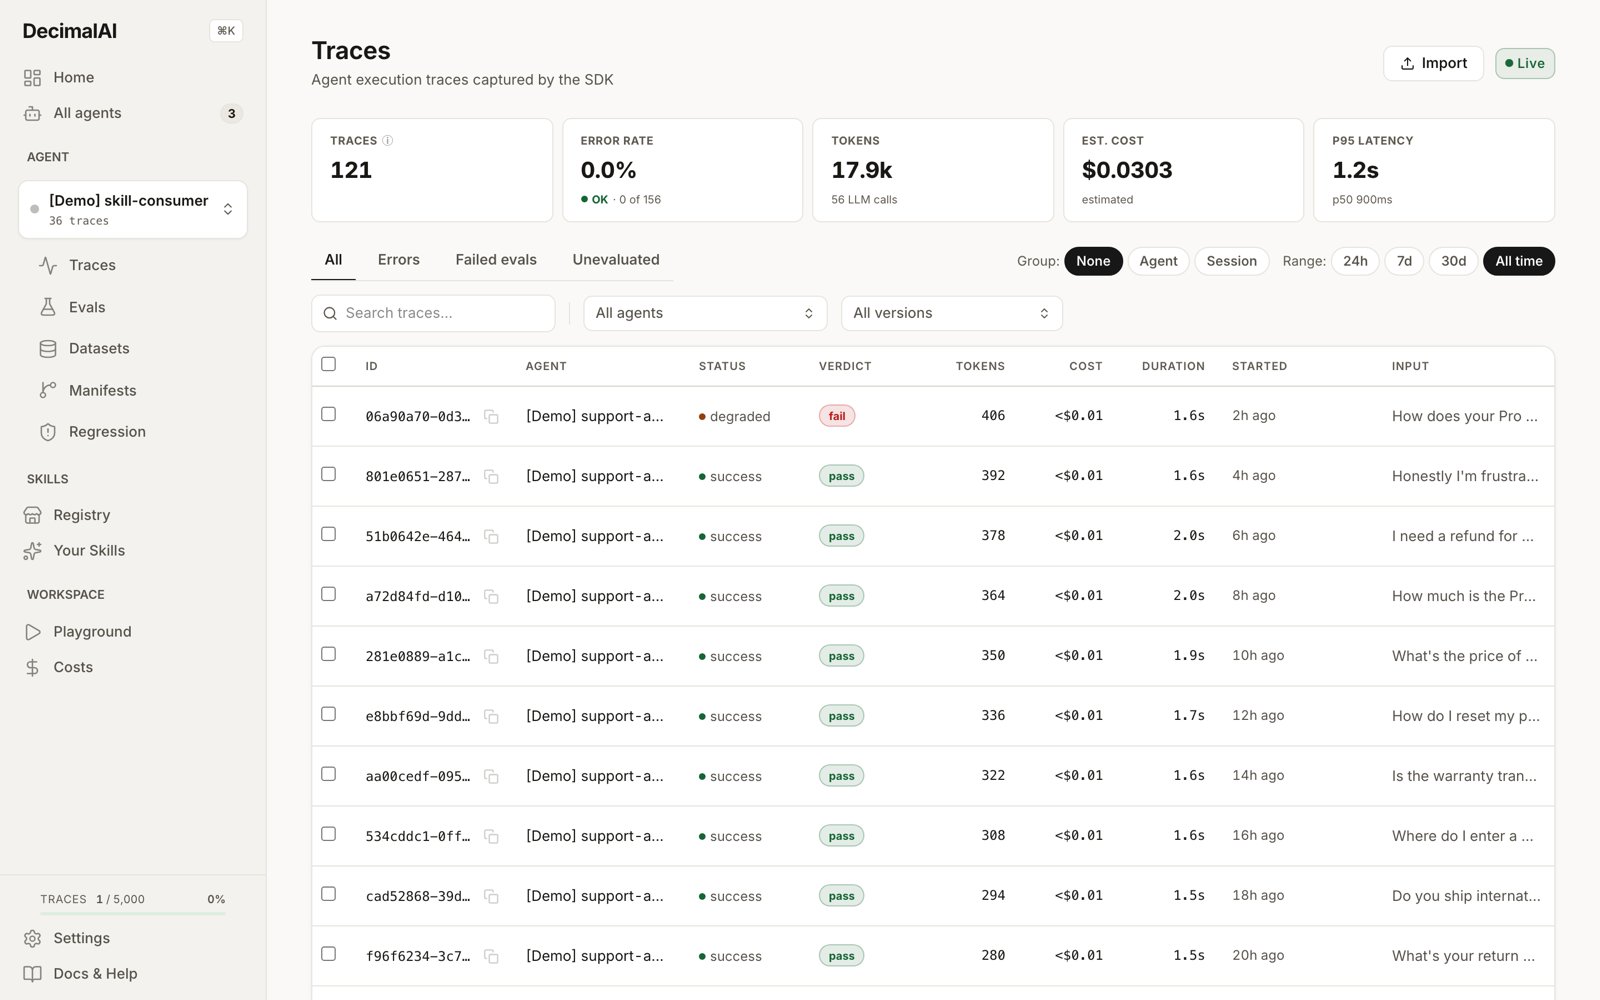
The Traces page, filterable by agent and by manifest version.
decimalai.evaluate() show here too, and their own page says evaluation in its header.
Trace schema
Every run is aRunTrace:
LlmCallRecord
Check your setup
WithDECIMAL_API_KEY set, one command checks your key, tests the connection and sends a test run, with no agent code:
decimalai-init-test. If it doesn’t appear on the Traces page within seconds, see the silent no-ops.
Turn tracing on
An agent built withagent_config() is traced already. Frameworks shows the line for each framework. For tracing alone, with no prompt or skills from DecimalAI, use a flag:
skills=False or set DECIMALAI_SKILLS=0. Frameworks with no DecimalAI integration go through OpenTelemetry.
Zero-code setup (environment variables)
DecimalAIPlugin() in your App.
Manual tracing
For a plain function, use the decorator. The SDK reference has the rest.Next Steps
Evaluations
Test a change, and score production runs.
Troubleshooting
Runs not showing up, or missing a verdict?